Sign-pair data used in the 2009 entropy analysis
The analysis used Mahadevan's concordance; the supporting online material of the Science paper describes the corpus preparation and the comparison sequences.
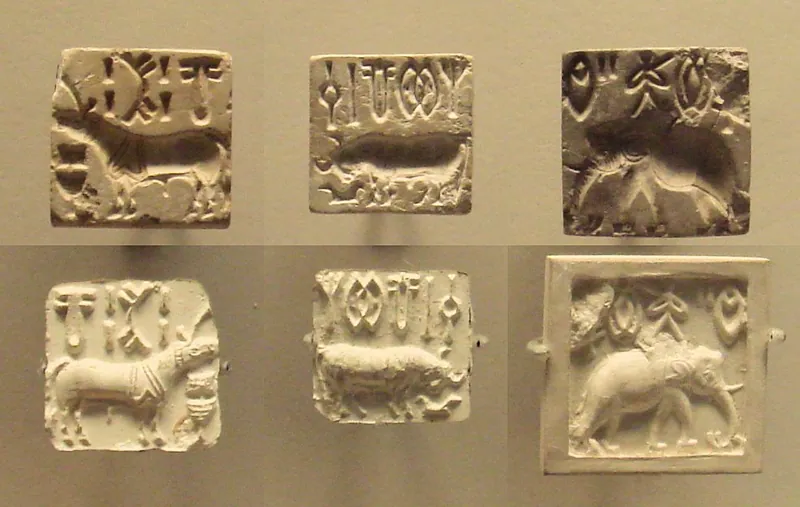 Indus scriptVersion 1.0Licence The maker'sUpdated 26 Oct 2026
Used by
0methods
0runs, with their results
0research sessions